Can a decision model find Waldo?
We gave nine image-input decision models 66 Where’s Waldo scenes and a picture of Waldo to answer 1 question: “Where’s Waldo?”
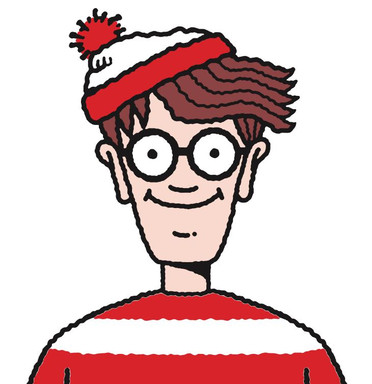
Who found him
66 scenes, one search each. Select a model to step through the scenes it missed, with its pick next to the real Waldo.
Accuracy, cost, speed and confidence
Smaller tiles make every model better at the job. At 128 px, here is what each model’s found rate costs in dollars and seconds, and how well its confidence matches how often it is right.
Found rate by tile size
Each line is one model. Tiles are enlarged to 384 px before they are sent.
Cost efficiency: found rate against cost
128 px tiles. Cost is the billed OpenRouter price to search one whole scene (log scale).
Speed vs quality
128 px tiles. Typical search is the median time to search one whole scene, with 16 tile requests in flight (Jev 1.14: one request).
Confidence alignment
Each model’s found rate against how sure it was, on average, of the tile it chose.
Where they looked instead
Places where three or more models settled on the same wrong spot, next to the real Waldo in the same scene.
Every scene, every pick
Pick a scene from the list to see where every model looked, then pick a model to see its choice up close. Bars under each scene count the models that found Waldo there.
Each row is a model and each column a scene, from the scene most models found to the one fewest did. Select a square to see that model’s pick.
How we scored
Everything that went into the numbers above.